Every day, your fitness wearable quietly samples your heart rate, your motion, your skin temperature and your blood oxygen, thousands of times, without you asking it to. What turns that silent stream of numbers into a morning readiness score is not the sensor itself. It is the ai fitness wearable data architecture: the layered pipeline of software and models between the device on your wrist and the coaching on your screen. At theweirdnewsblog.com we dig into how emerging technology works under the hood, and this architecture is one of the most interesting invisible systems in consumer tech.
The design of this pipeline matters. Connect a language model directly to raw sensor readings and you get three predictable problems: slow answers, privacy headaches and coaching that mistakes a restless night for a training crisis. The systems that work well instead follow a disciplined, layered design, where each stage fixes one specific class of failure before the data moves on.
Key Takeaways
– The ai fitness wearable data architecture explained in one line: a layered pipeline that moves raw sensor signals from the device through cleaning, rules and AI into trustworthy coaching.
– Key benefits: cleaner metrics through normalization, faster feedback through on-device processing, stronger privacy through encrypted user-scoped storage, and safer coaching through rule-based guardrails.
– Most modern wearables use a hybrid design: quick decisions happen on the device (edge AI), while deep analysis and long-term trend detection happen in the cloud.
What Is AI Fitness Wearable Data Architecture?
AI fitness wearable data architecture is the complete technical stack that collects, cleans, stores, analyzes and acts on biometric data from fitness wearables. Think of it as the journey a single heartbeat measurement takes: from the optical sensor on your wrist, through Bluetooth to your phone, into a database, through cleaning and analysis, and finally into a sentence like “your recovery looks strong.”
The journey is deliberately split into layers. Each layer has one job, and each job exists because skipping it causes a failure users notice: gaps from bad sync, fake heart-rate spikes from uncleaned motion artifacts, privacy risk from weak storage design, or a model inventing advice that could genuinely hurt someone.
Which Sensors Feed the Pipeline and What Data Does Each Produce?
Modern wearables carry an array of sensors, and each contributes a different signal to the pipeline.
| Sensor | What It Measures | What the Pipeline Derives |
|---|---|---|
| Optical heart-rate sensor (PPG) | Blood-volume pulses in the wrist or finger | Heart rate, resting heart rate, HRV |
| Accelerometer | Acceleration along three axes | Steps, distance, activity type, workout detection |
| Gyroscope | Rotation and orientation | Exercise form, swimming stroke type, fall detection |
| Skin-temperature sensor | Surface temperature trends | Sleep quality signals, illness or cycle indicators |
| SpO2 sensor | Blood-oxygen saturation | Altitude adaptation, sleep-apnea screening signals |
| GPS | Position and speed | Running routes, pace, distance |
Two things stand out. First, many of the most valuable metrics, like HRV, sleep stages and stress scores, are not measured at all. They are estimated by machine-learning models from simpler signals such as motion, heart rate and temperature. Second, the quality of everything downstream depends on the sensor layer. A loose watch band or a bumpy bike ride injects noise at the source, which is why the next layers exist.
How Does Raw Sensor Data Become a Coaching Suggestion?
Production systems typically use an event-driven flow with about seven stages, each handing cleaner, safer, better-structured data to the next.
| Layer | What It Does | What Breaks If It Is Skipped |
|---|---|---|
| 1. Ingestion | Pulls data through device SDKs, HealthKit, Google Health Connect or unified third-party APIs | Gaps, missed syncs, duplicate records |
| 2. Normalization and cleaning | Aligns timestamps, unifies units, removes duplicates, filters outlier spikes from sensor movement | Coaching built on noisy or doubled readings |
| 3. User data store | Holds encrypted, user-scoped time-series metrics | Privacy and compliance exposure |
| 4. Rules and guardrails | Deterministic threshold checks before any AI gets involved | Unsafe prompts reach the model |
| 5. AI orchestration and RAG | Combines the user’s metric history with vetted sports-science knowledge | Generic or invented advice |
| 6. Coaching engine | Generates adaptive guidance using ML models and a language model | No personalization or context |
| 7. Output validation | Screens the final suggestion for injury risk and dangerous demands | Harmful recommendations reach the user |
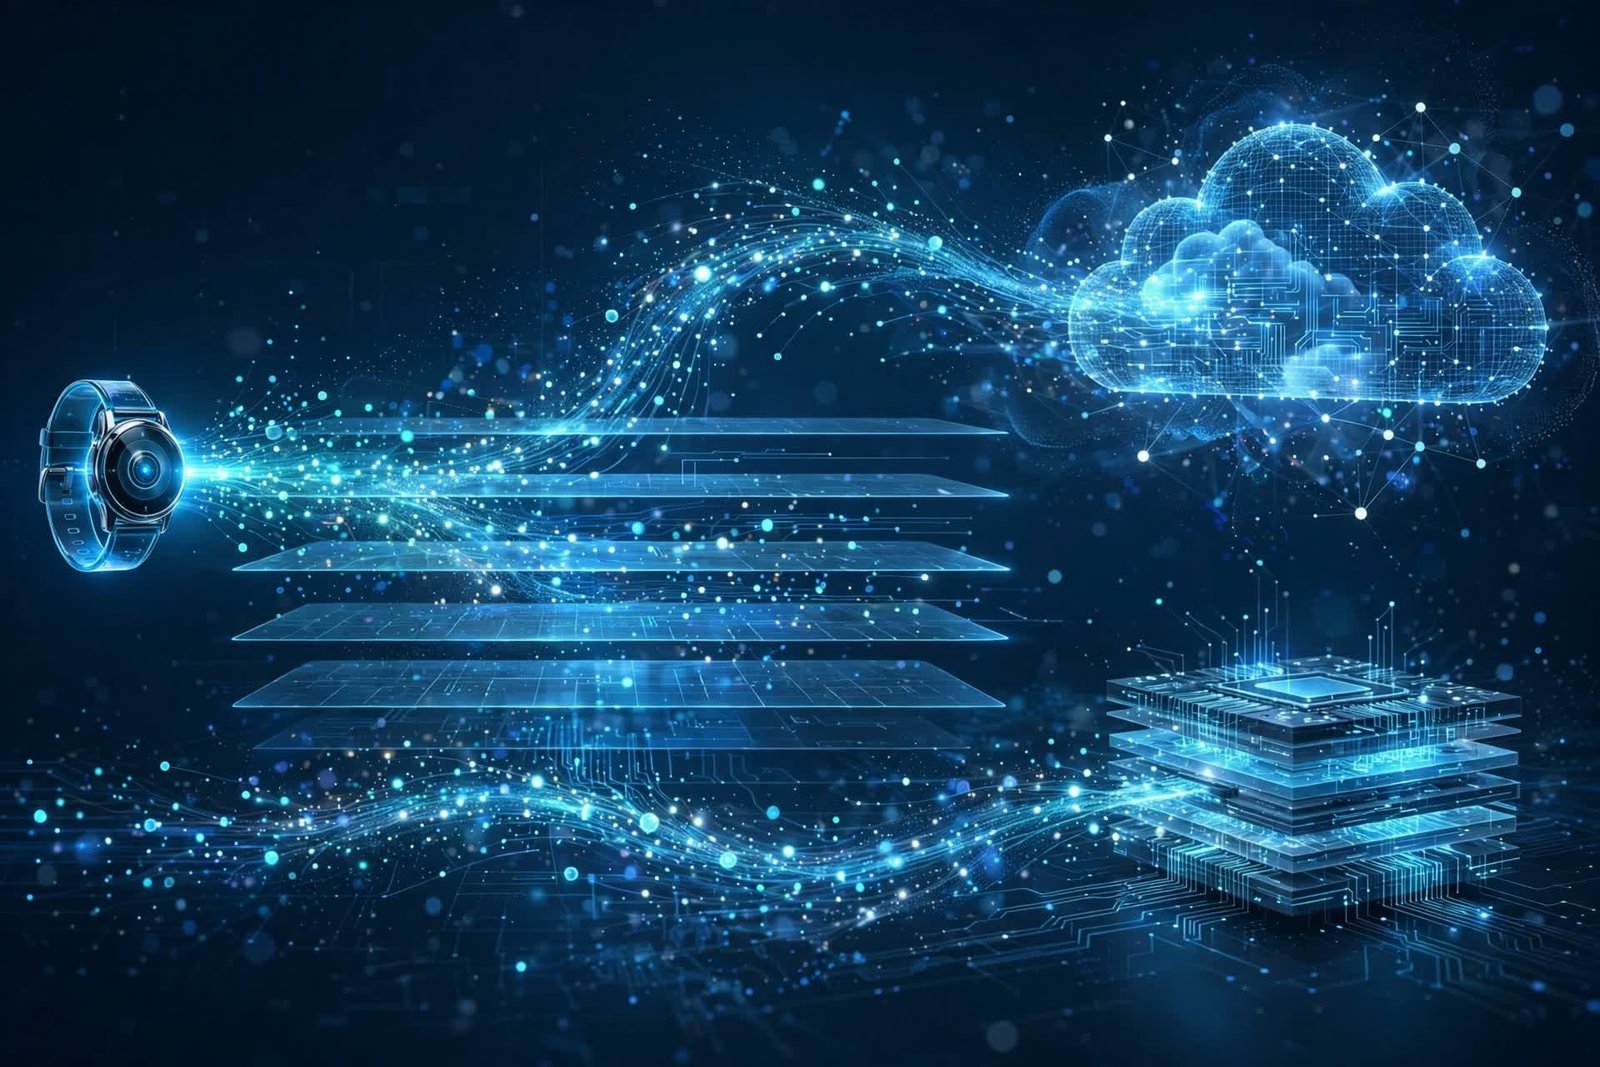
A concrete example: you wake up with HRV well below your baseline. The rules layer notices before the AI does and can skip the language model entirely, serving a standard rest protocol instead. On a normal day, the orchestration layer pulls your recent training load, retrieves vetted guidance from its knowledge base, and builds one rich prompt for the coaching engine. Finally, the output validator checks the suggestion against your flagged knee injury and removes any movement the model should never have proposed.
Where Does Edge AI Fit Compared to the Cloud?
Not every computation should travel to the cloud. Edge AI means running models directly on the wearable or the paired phone, right where the data is born. Cloud processing means shipping data to a server and waiting for the answer to come back.
Modern wearables mostly use a hybrid of the two. Time-sensitive work happens on the device: detecting a fall, estimating heart rate in real time, classifying an activity as walking or running. These jobs need millisecond answers, must work without a phone signal, and benefit from raw biometrics never leaving the body. Deeper work happens in the cloud: multi-week trend analysis, recovery modeling and the language model that writes coaching in natural sentences. The cloud has the memory and the compute; the edge has the speed and the privacy.
The direction of travel is clear: more interpretation on the wrist, less raw data on the wire.
How Do Apps Handle Data From Different Wearable Brands?
This is one of the hardest problems in the stack, and the answer is normalization. Every brand reports the world a little differently. One device samples heart rate every second; another reports a five-minute average. Energy may arrive in kilocalories or kilojoules. Timestamps need to land in UTC with the user’s local offset kept alongside, because sleep crosses midnight and people travel. Even definitions differ: one provider’s resting heart rate may be a nightly minimum while another’s is a daytime average, and HRV itself can be reported as SDNN by one source and RMSSD by another. A pipeline that ignores this will happily average two numbers that do not mean the same thing.
In practice, apps read local metrics through Apple HealthKit or Google Health Connect, and reach brands like Garmin, Whoop or Oura through server-to-server sync, often via unified third-party APIs that aggregate several streams into one place. The normalization layer converts every payload into a single common schema, flags daily totals so they are never summed with their underlying intraday records, and drops duplicate background syncs. This unglamorous plumbing is the difference between numbers users trust and an app they quietly stop opening. It is also exactly the kind of foundational data-science work taught in depth by a practical data science course for learners, since data cleaning and schema design are where most real-world machine-learning projects are won or lost.
What Keeps the AI Coach From Giving Unsafe Advice?
Generative models are fluent but not reliably careful, so the architecture never trusts them with the final word. Safety is enforced in three places. Before the model runs, deterministic rules review the data: unusual cardiovascular readings, a flagged injury or an HRV crash can trigger a fixed, safe protocol with no model involvement. During generation, retrieval-augmented generation grounds the prompt in verified sports science and the user’s actual history. After generation, an output validator screens for injury risk, impossible demands and hallucinated exercises.
Teams also face a broader decision: which model generation should power the system, and when is a newer one worth adopting? That trade-off is not unique to fitness. Any team adopting AI weighs new capabilities against stability, cost and migration pain, the same calculus we explored when asking whether you should switch to Kling 4.0 or wait. The principle carries over: adopt the model your guardrails are built for, and re-test everything when it changes.
How Is Health Data Privacy Protected in This Architecture?
Privacy is a structural feature of a good architecture, not a policy page. The standard pattern is isolation by design: biometric histories live in encrypted, user-scoped databases, commonly time-series stores built for this workload, with each data scope explicitly defined and enforced. Critically, raw health records are kept separate from model training data and from the general knowledge base, so your sleep history cannot leak into what the model tells someone else.
Edge processing helps too. Every inference that runs on the device is one less trip your biometrics take across the network, which reduces exposure and simplifies compliance with regulations like GDPR and HIPAA-adjacent expectations in the US. Recent industry research suggests buyers now judge fitness trackers more on verified metrics, app quality and privacy controls than on physical design. The software layer, including how it treats your data, has become the product.
What Are the Main Benefits of This Architecture?
A well-designed pipeline delivers practical payoffs: more accurate coaching from real signal instead of sensor noise; faster feedback from on-device inference that answers in milliseconds and works offline; stronger privacy from encrypted, scoped storage and edge-first processing; safer AI behavior from guardrails before and after the model; better retention, because consistent, safe, personalized advice is why people keep wearing the device; and compliance headroom, because a layered, auditable design maps onto GDPR and HIPAA expectations far more easily than a tangle of cloud functions.
The honest bottom line is that the architecture has to come before the feature roadmap. Device makers themselves are shipping native AI coaches, which raises the bar for every third-party app. Teams that bolt a chatbot onto raw wearable data end up spending their second year rebuilding the layers they skipped. Teams that design the full device-to-coach pipeline up front get coaching their users can trust, and trust is the only metric that compounds.
Frequently Asked Questions
What is ai fitness wearable data architecture in simple terms?
It is the system that turns raw numbers from your smartwatch into useful advice. It collects sensor data, cleans it, stores it securely, applies safety rules, runs AI analysis and produces coaching you can act on.
Does my smartwatch run AI on the device or in the cloud?
Mostly both, in a hybrid design. Quick tasks like activity detection and heart-rate estimation run on the device for speed and privacy. Heavier work, like long-term trend analysis and the language model that writes coaching, runs in the cloud.
Why do two different wearables show different HRV numbers for the same night?
They may be measuring different things under the same label. HRV can be reported as SDNN by one brand and RMSSD by another, and sampling windows differ. Normalization layers exist to map each brand’s fields to a common definition before any comparison.
How do fitness apps get my data from brands like Garmin, Whoop or Oura?
Through two routes: Apple HealthKit or Google Health Connect for local metrics, and server-to-server sync, often via unified third-party APIs that aggregate several brands into one feed, which the app then normalizes.
Is my biometric data used to train AI models?
In a well-designed architecture, no. Good systems isolate your encrypted health records from model training data by design, with enforced data scopes. Practices vary by company, so check the privacy settings and data policy of any app you use.
Can an AI coach replace a human trainer?
Not fully. AI coaches excel at pattern detection across thousands of data points and at consistent daily guidance. Human trainers still win on nuanced judgment, technique correction, accountability and medical complexity. The strongest setups combine both.